October 19th Research Briefing
A weekly publication of the top three papers from arXiv last week. Papers with arXiv v1 published 2026-10-12 through 2026-10-16 UTC.
Contents
- LENS: LLM-guided analysis finds 95 unknown core-network bugs
- MCP-FSD: approved MCP tools leak host credentials
- VulnSAGE: checked LLM verdicts turn SAST alerts into fixed bugs
LENS: LLM-guided analysis finds 95 unknown core-network bugs
LENS found 95 previously unknown vulnerabilities in 4G core-network implementations that speak Diameter: 17 in two open-source stacks (Open5GS and Kamailio) and 78 in two commercial ones. Both commercial vendors confirmed every reported issue, and the Open5GS reports have 5 CVE and 7 CNVD identifiers so far. Impacts include persistent LTE service loss, leaked authentication vectors, subscriber tracking, and fast battery drain.
This matters because operators and vendors told the researchers that exposed core-network elements without Diameter TLS are not rare. An attacker who can impersonate a network element can then send crafted field values, and plain LLM judgments on which fields are exploitable can be unreliable.
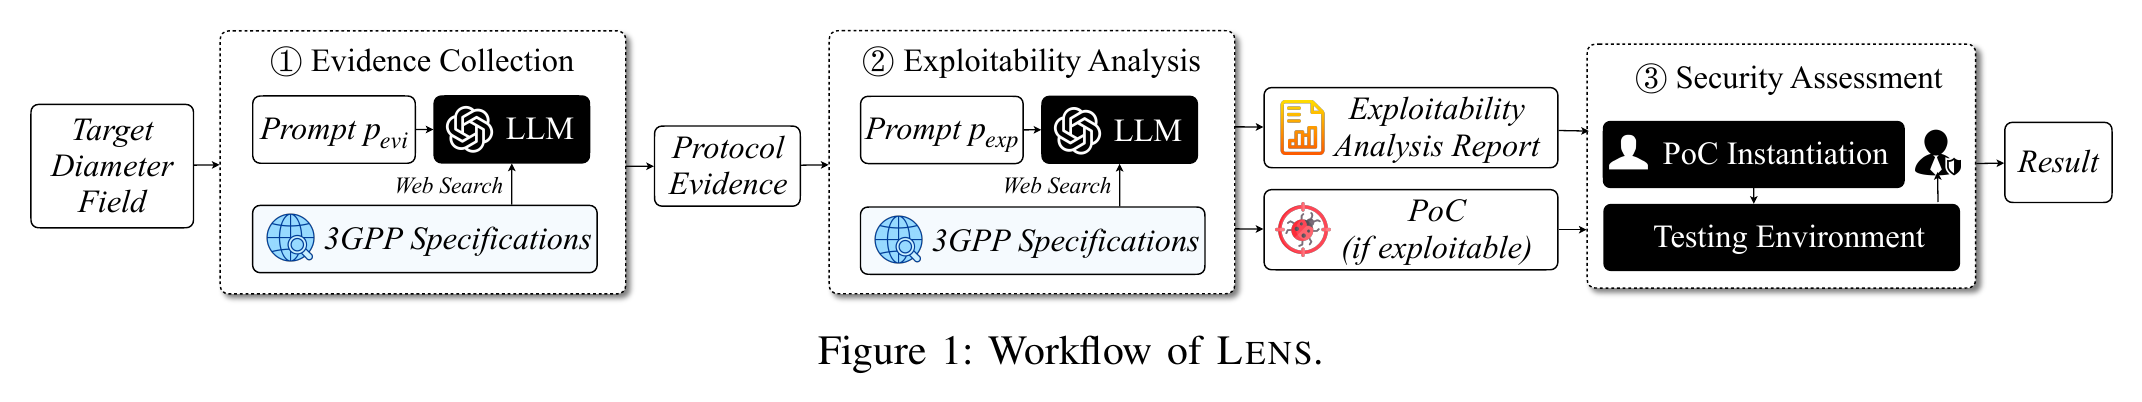
LENS infers the expert analysis discipline from existing exploit writeups and turns it into a prompt. A second prompt, learned from failed LLM writeups, tells the model which 3GPP evidence to collect. The model then rates each field and writes a PoC, which runs in a test network.
Across 766 fields in the S6a and Cx interfaces, 204 (26.63%) are exploitable under the threat model. Run unchanged on 16 more protocols, LENS confirmed 118 new issues in open-source implementations.
Authors: Wei Yi, Changlong Han, Xue Zhang, Qiao Zhang, Yi Chen, Jin Cao, Di Tang, Yulong Fu, Ben Niu, and Hui Li (paper, pdf, artifact). Di Tang: GitHub.
MCP-FSD: approved MCP tools leak host credentials
MCP-FSD confirmed 150 vulnerable Model Context Protocol (MCP) server instances where a benign-looking tool call reads host files outside the tool's declared scope. The researchers reported 13 findings through coordinated disclosure, including two CVEs in Anthropic's Git MCP Server: CVE-2025-68143 in git_init and CVE-2026-27735 in git_add. Both are patched upstream.
The gap exists because the client's approval prompt checks the tool name and arguments, while a local stdio server runs with the user's full filesystem permissions. The paper calls this filesystem capability laundering: an attacker-steered path makes an innocent tool return SSH keys or dotfiles.
MCP-FSD catalogs servers, uses an LLM to draft a least-privilege boundary per tool, and plants credential fixtures outside it. Each candidate then runs three cases: an unsandboxed attack, a sandboxed benign call, and a sandboxed attack.
Across 21,097 servers from nine registries, 787 of 4,806 triaged servers (16.4%) show filesystem capability despite a non-filesystem category. In 144 of the 150 confirmed cases, a bare traversal path was enough.
Authors: Zeqian Huang, Mingyue Tang, Aonan Guan, Qiming Sun, and Pengzhou He (paper, pdf). Aonan Guan: GitHub, LinkedIn.
VulnSAGE: checked LLM verdicts turn SAST alerts into fixed bugs
VulnSAGE reproduced 104 defects at runtime from 45,440 alerts that five SAST tools raised on the 200 most-starred C/C++ projects on GitHub. Maintainers confirmed 24 of the 26 defects they have answered so far, including ten previously unknown defects, and nine of those are already fixed.
This matters because most SAST output is noise, and the code that decides a report often sits far from the flagged line. LLM triage can read that code, but its verdicts are hard to check.
VulnSAGE slices from the report over a program graph that keeps dependencies plus the structure that explains them, such as which object a helper call receives. The model writes each judgment as a CLAIM fact that cites program relations. Program analysis checks those citations, and only facts whose premises hold count toward the verdict. Supported true positives then go to PoC generation and execution.
On 187 labeled reports, it rejects 89 of 97 false alarms and keeps 85 of 90 real defects. Under the same PoC procedure, 25 of its positive verdicts reproduce, against three for LLM4SA. In one confirmed libtiff case, a generated BigTIFF input trips AddressSanitizer.
Authors: Jinbao Chen, Zixiang Zhou, Yu Zhang, and Yihong Wu (paper, pdf).